Modern applications generate telemetry across every layer of the stack, but understanding what changed and why often remains difficult. Database signals frequently live in separate workflows, forcing teams to switch between dashboards, correlate disconnected data, and piece together performance issues without the full operational context.
With MongoDB 9.0, we’re making it easier to understand database behavior and accelerate troubleshooting. Now we’re introducing three observability enhancements that help teams move from detection to diagnosis faster:
OpenTelemetry enhancements that bring Atlas metrics, logs, and events into the observability tools engineering teams already use.
A redesigned Metrics UI that provides a clearer, cluster-level view of health and performance.
Query Shape Insights for write operations, extending query-level diagnostics beyond reads.
Together, these observability capabilities help teams spend less time hunting for answers and more time resolving issues, optimizing performance, and maintaining reliable applications.
Bring MongoDB Atlas telemetry into the observability stack
When critical database context lives in separate systems, troubleshooting can require switching tools and manually piecing together what’s changed; MongoDB Atlas helps close that gap by bringing database telemetry into the observability workflows teams already use. Now, Atlas Events Integration provides teams with a new source of operational context.
Atlas Events Integration enables customers to export Atlas Activity Feed events—including cluster modifications, user management changes, network access updates, and project or organization configuration changes—to OpenTelemetry-compatible destinations and other supported integrations. By making these events available alongside existing observability data, teams can better understand not only that something changed, but what changed.
Combined with MongoDB Atlas metrics and log integrations, teams can correlate performance issues with the operational activity that may have contributed to them. For example, a latency spike can be viewed alongside recent configuration changes, access updates, or scaling events, helping teams move more quickly from symptom to root cause.
Together, metrics, logs, and events provide a more complete picture of database operations. The result is a more connected observability experience that helps teams troubleshoot faster, reduce operational complexity, and gain the context needed to resolve issues with confidence.
A simpler way to understand cluster health
External integrations help teams bring Atlas into a broader observability strategy. The new Metrics UI makes it easier to understand cluster health directly in Atlas.
The redesigned experience replaces a fragmented metrics workflow with a single unified view of cluster metrics. Metrics are presented in a clearer, cluster-level experience, with node selectors that help users focus on the systems relevant to an investigation.
This matters when time is limited. Platform engineers, SREs, and DBAs should not have to navigate across multiple pages to build a picture of cluster behavior. Application developers and engineering leads should be able to map an application symptom to the relevant Atlas signal without needing to become observability specialists. A more consistent workflow helps both groups spend less time searching and more time diagnosing.
Figure 1. The redesigned Atlas Metrics UI provides a unified view of cluster performance and health, with streamlined navigation, cluster-level metrics, and node selection controls.
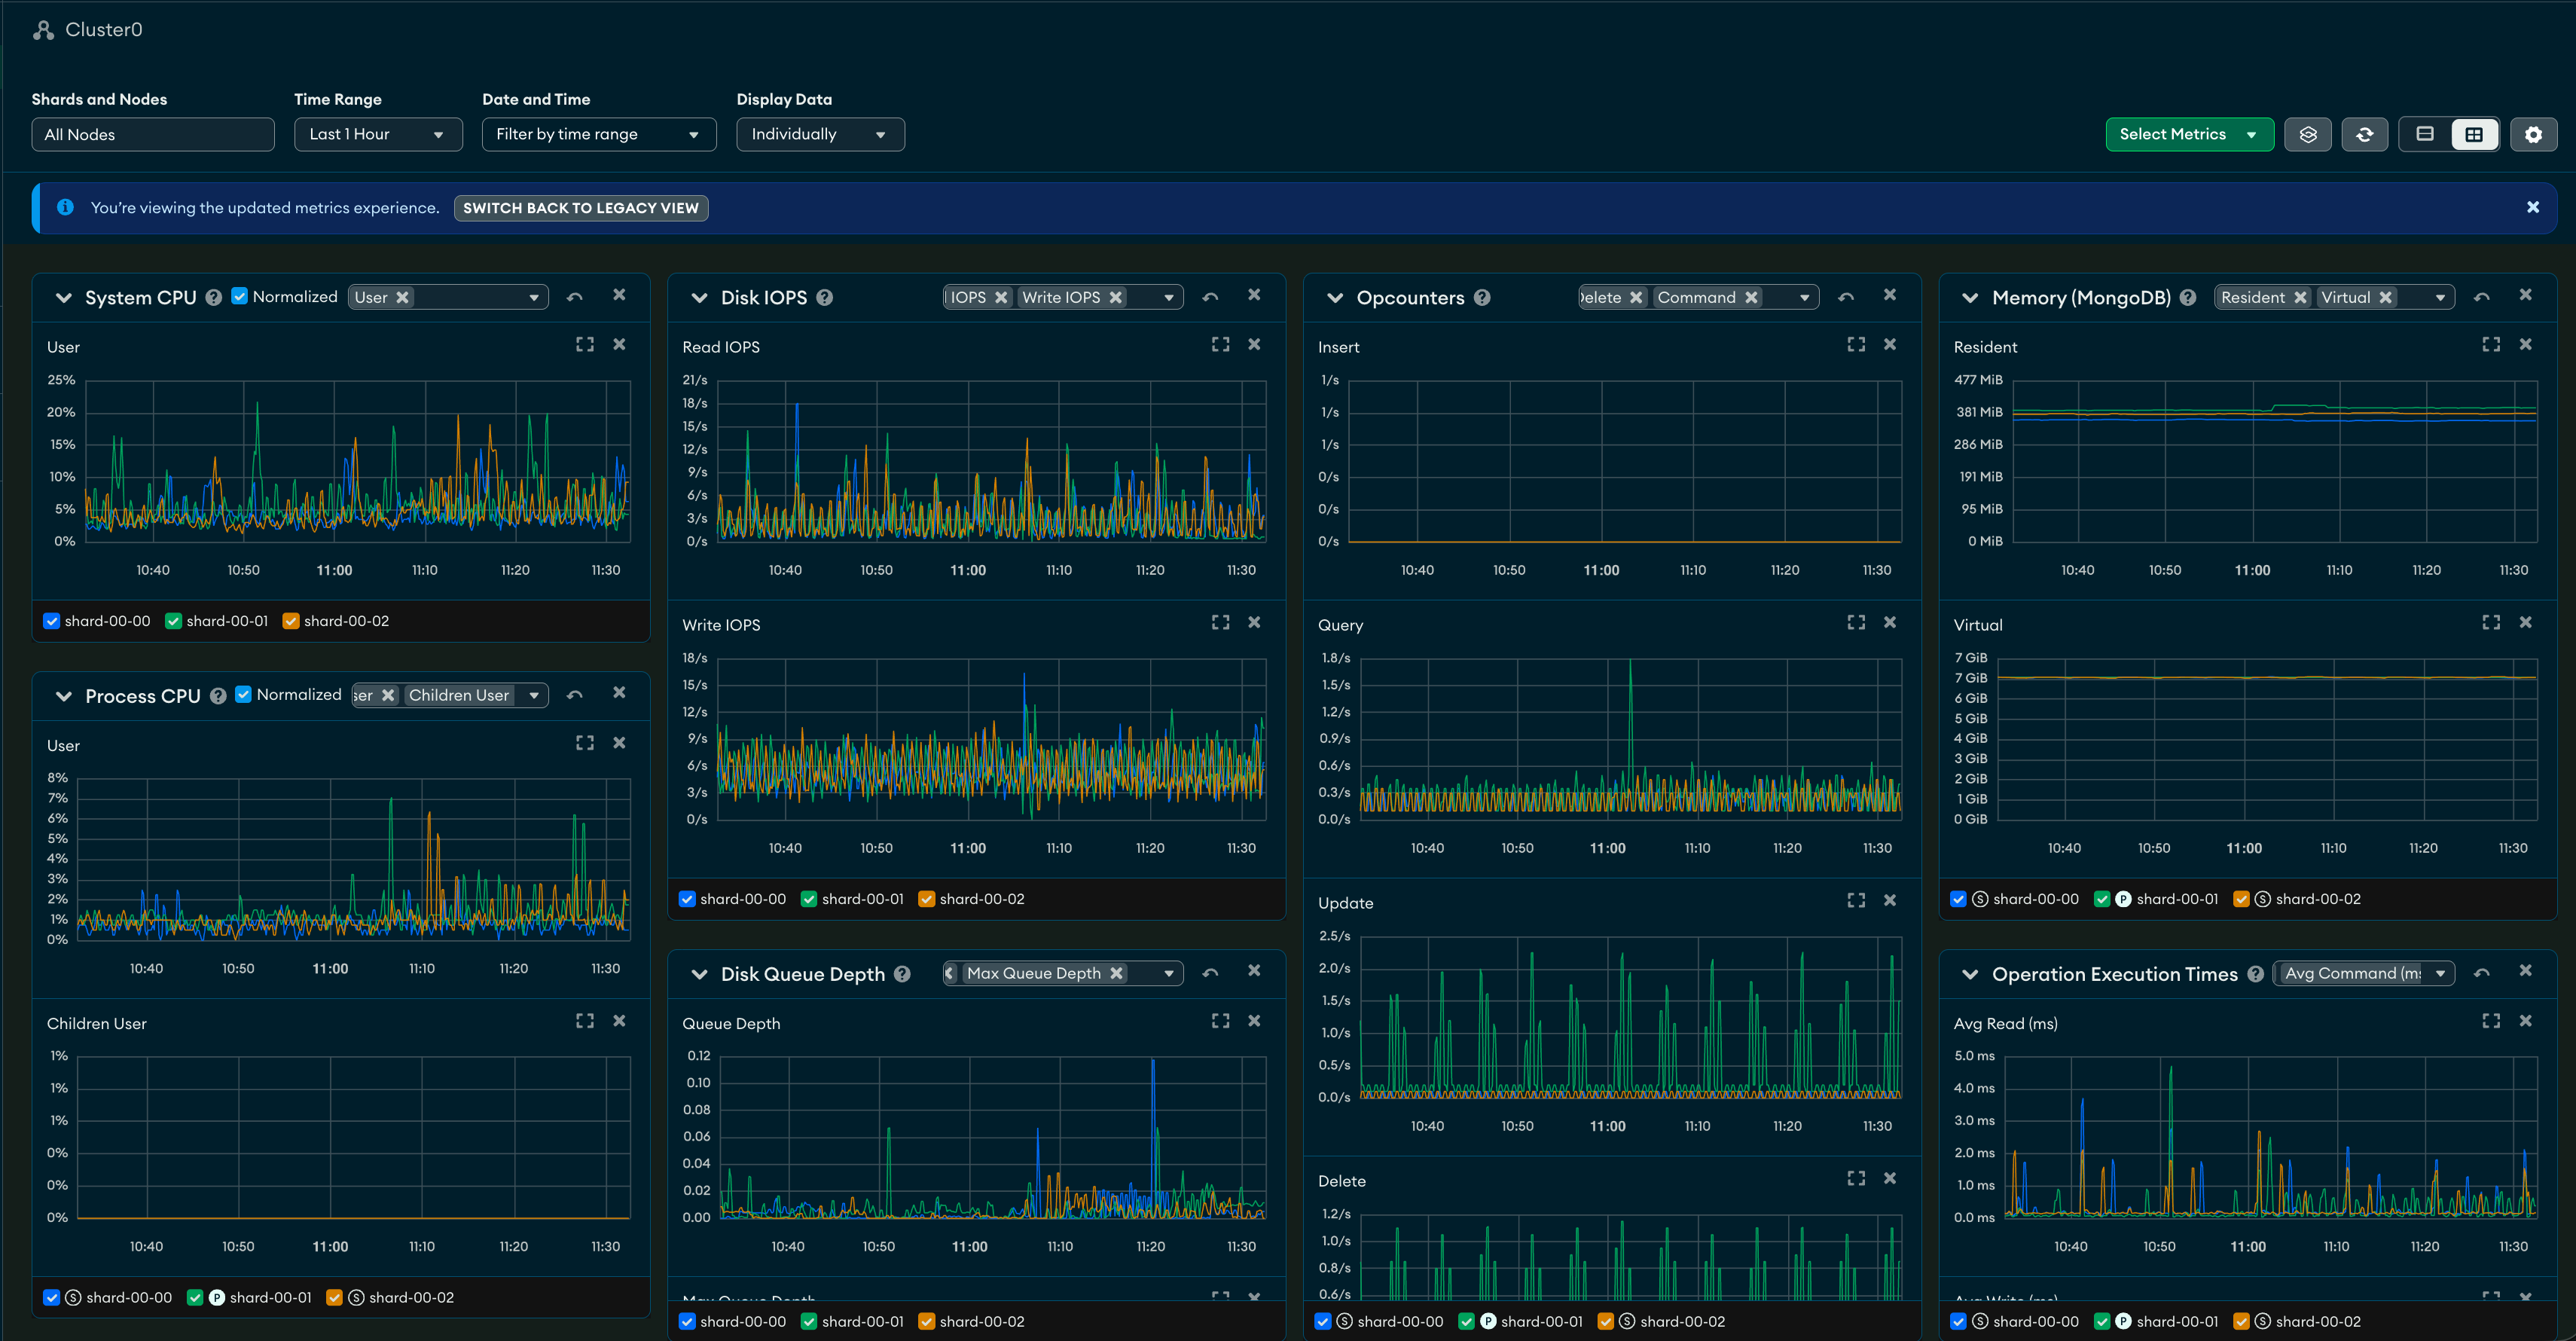
The new experience is also designed to provide a stronger foundation for future coverage of metrics and more reliable service. Existing links to the legacy experience continue to work through redirects, and surrounding workflows, including third-party integrations, Atlas Admin API metrics endpoints, alert delivery, billing, and Performance Advisor or Query Insights, are not changed by the UI refresh.
Query Shape Insights now covers writes
Application performance is shaped by both reads and writes. While read visibility is critical, inefficient write operations can also drive latency, consume excess resources, and increase infrastructure costs. With Atlas clusters running MongoDB 9.0 and later, Query Shape Insights now supports insert, update, and delete operations, giving teams a more complete understanding of how query patterns affect workload performance.
With write support, teams can:
Identify inefficient update and delete operations, including unindexed filters and large updates.
Analyze the impact of writes using metrics such as Docs Matched, Docs Modified, Docs Upserted, Docs Inserted, and Docs Deleted.
Examine write-related index activity, including Keys Inserted and Keys Deleted.
Use CPU Time and other performance metrics to understand resource utilization and reduce unnecessary infrastructure costs.
Filter and investigate query behavior across replica sets and sharded clusters.
On MongoDB 9.0 and later, Query Shape Insights uses a lightweight 1% random sample of read and write operations. This provides visibility into production workloads with low overhead. Note that displayed totals reflect only the sampled operations — roughly 1% of the actual workload—not the full volume. Query shapes that run infrequently may not appear.
Query Shape Insights groups operations by shape — capturing the structure of the query without its specific values—so thousands of individual queries collapse into a handful of shapes. Teams can identify recurring workload patterns, connect performance issues to the queries driving them, and validate the impact of indexing or application changes.
Available for dedicated Atlas clusters running MongoDB 8.0 and later, Query Shape Insights provides a more complete view of workload behavior and, with MongoDB 9.0, a faster path to optimizing both reads and writes.
Observability that fits the way teams operate
As applications grow more distributed and operational environments become more complex, teams need observability tools that provide both visibility and context.
MongoDB 9.0 helps organizations integrate database telemetry into existing observability workflows, simplify performance investigations within MongoDB Atlas, and better understand the query patterns that affect application performance.
Whether you’re routing Atlas metrics, logs, and events into your broader observability platform, investigating cluster health directly in Atlas, or optimizing read and write workloads with Query Shape Insights, the goal is the same: helping teams move faster from detecting an issue to understanding its cause and taking action. Observability isn’t just about collecting signals—it’s about turning those signals into operational insight.
Next Steps
Get started with these capabilities today for free at mongodb.com/atlas.
Configure your first OpenTelemetry metrics endpoint through the Atlas UI or Terraform, export Atlas logs and events, explore the new Metrics UI, and use Query Shape Insights to investigate read and write performance on your dedicated clusters.